AtlasVid
Efficient Ultra-High-Resolution Long Video Generation
via Decoupled Global-Local Modeling
NeurIPS 2026
Dartmouth College
* Equal contribution
Generate long, detailed videos with decoupled global and local modeling.
Overview
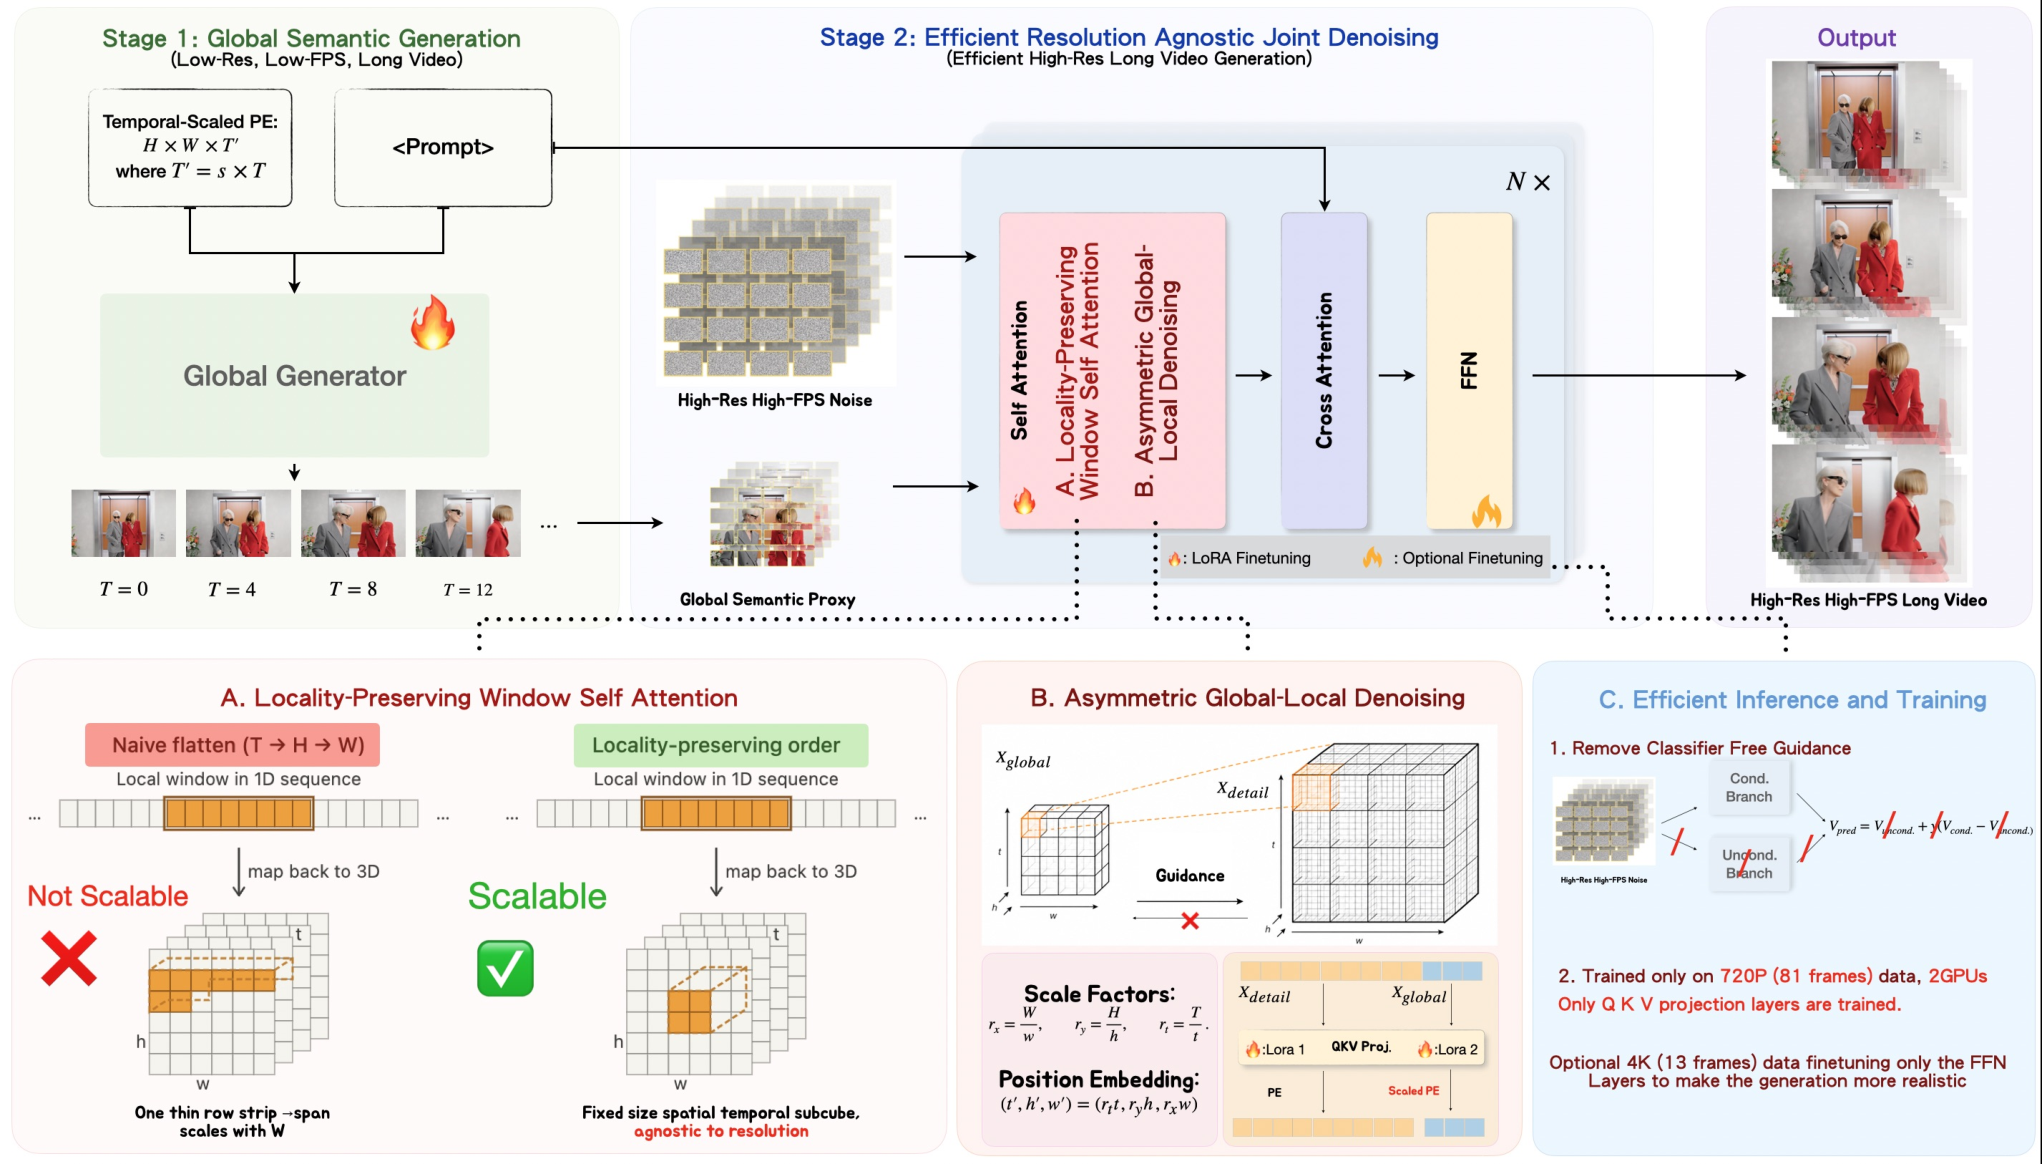
AtlasVid separates global scene structure from local visual detail. A low-resolution, low-frame-rate semantic proxy guides a detail generator through hierarchical, locality-preserving attention. Trained at 720p with lightweight LoRA adaptation, the model scales to 4K and beyond without training on ultra-high-resolution long videos.
Temporally scaled RoPE extends the generation horizon, while aligned global guidance maintains coherence throughout a continuous shot.
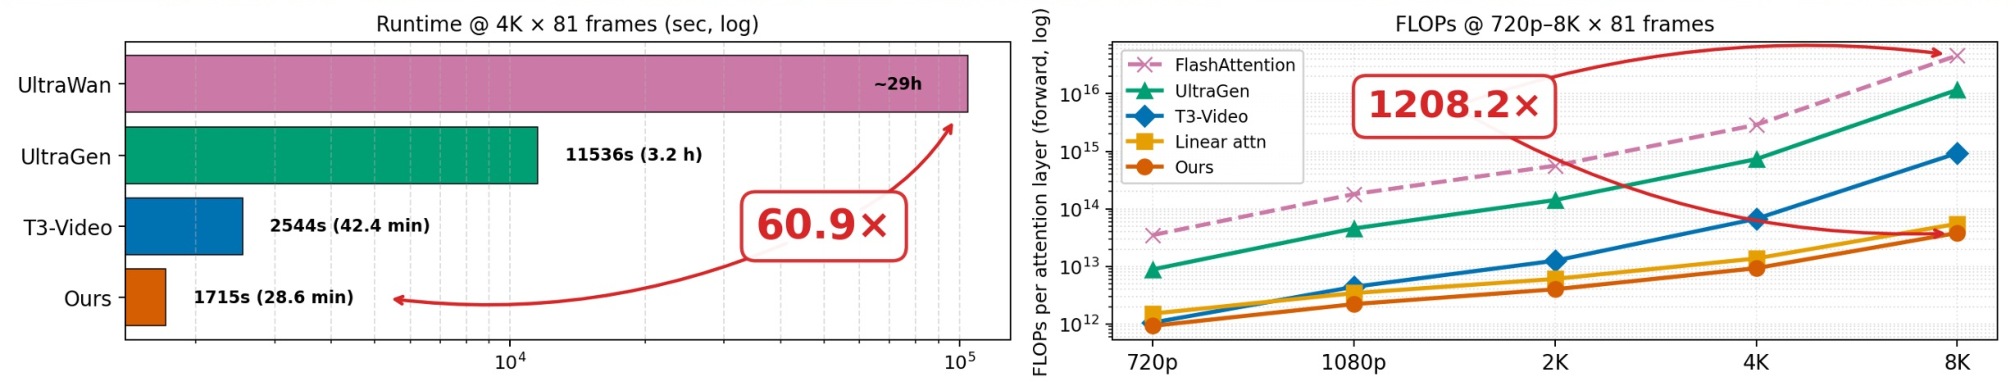
Runtime
4K · 81 frames
More results
4K source · 161 frames
Videos are compressed to 720p for web playback. Source resolutions are indicated above.
Method
A global semantic proxy establishes the scene and motion. The detail branch jointly denoises high-resolution tokens using local attention and aligned global guidance.
Ablation studies
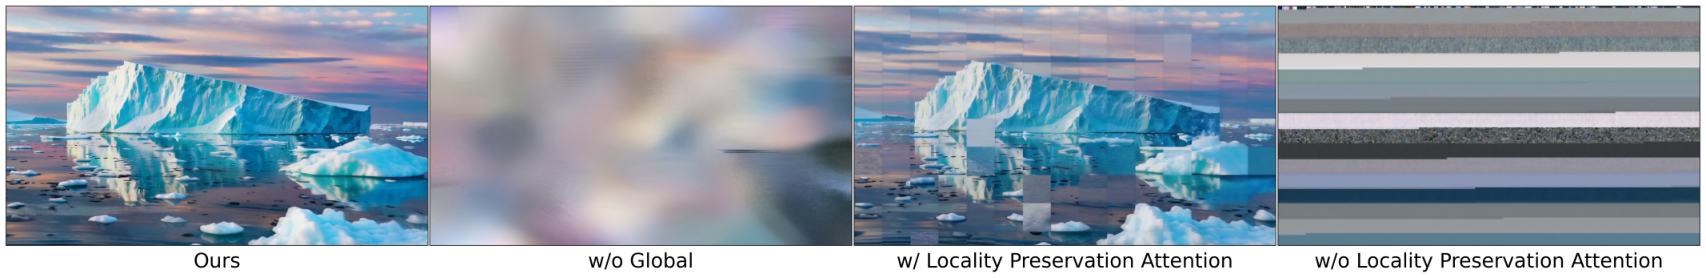
Global guidance and locality-preserving attention
Global guidance maintains scene consistency, while locality-preserving attention enables resolution extrapolation. All variants are trained at 720p and evaluated at 4K. For the locality comparison, attention between neighboring blocks is disabled to expose the block structure.
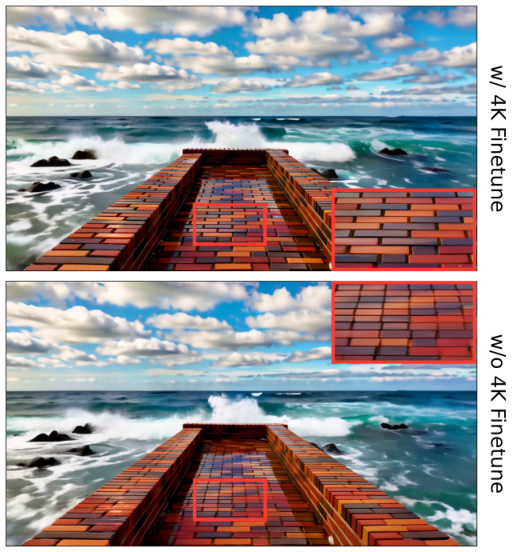
Optional 4K fine-tuning
The base model already generates plausible 4K detail. An optional refinement stage using short 4K clips further improves local realism, as illustrated by the brick textures.
BibTeX
@inproceedings{mai2026atlasvid,
  title={AtlasVid: Efficient Ultra-High-Resolution Long Video
         Generation via Decoupled Global-Local Modeling},
  author={Mai, Ziyang and Zhang, Yuyao and Tai, Yu-Wing},
  booktitle={Advances in Neural Information Processing Systems (NeurIPS)},
  year={2026}
}